This is source-based analysis, not a hands-on review. Our earlier Figure 03 explainer covered hardware and Helix 02 demos; the question here is transfer to unfamiliar homes.
Updated October 11, 2026: expanded the evaluation analysis and practical reading guide. The original publication date remains October 10, 2026.
What Figure tested
Figure's September 17, 2026 Helix 2.5 report describes toy tidying, towel folding and bed making across 30 unseen Bay Area homes. These are manufacturer-reported results, not independent testing.
“Zero-shot” concerns homes and objects; tasks were fine-tuned elsewhere. Each task used a fixed checkpoint, not selected using evaluation performance.
The report's chart shows 237/420 complete-task successes with Index human-behavior pretraining (56%), versus 35/420 without it (about 8%). The prose instead says 9% for the baseline; the two disagree. The comparison holds architecture, optimization, hyperparameters, task data and evaluation fixed; the baseline starts from random weights. It is not a competitor comparison.
Each policy had 140 trials per task. The Index results were 87 towel, 56 toy and 94 bed successes; baseline results were 12, 7 and 16 respectively. Whole-task completion was required; the appendix grades neatness separately, and the chart specifies a minimum bedding grade. The appendix imposes timeouts and counts safety interventions as failed trials.
How to interpret the result
The useful inference is about the training recipe: under this controlled comparison, prior learning helped a robot apply specified behaviors in unfamiliar settings. That is a more informative question than whether a selected video looks impressive. It still leaves a gap between performing a chore under an evaluation procedure and taking responsibility for it in your home.
Do not treat the headline percentage as your household's probability of success. Your furniture, tolerated mess, interruptions and definition of a finished job may differ. Trial counts help interpret a rate, but do not by themselves explain how results vary between homes. To judge consistency, ask for per-home breakdowns, variation across repeats and failure causes.
Read the task-level results before the pooled rate. If your priority is laundry, performance on other chores cannot answer whether your towels end up where you want them. Ask to see the exact end condition, time allowed and what happens to an interrupted attempt before comparing headline scores.
Read the comparison as an experiment
A controlled comparison is useful because it narrows the explanation for a change. Imagine comparing two robots where one has better cameras, more practice, a newer controller and an easier room. A higher score would not tell you which change mattered. Holding those choices constant makes a narrower question answerable. Here, the question is whether the initialization supplied by pretraining helps the subsequent task learning transfer. It is a question about a training approach, not a contest between every available robot.
That distinction changes how to read the weak baseline. A policy trained from scratch is a reference point within the experiment. It should not silently become a stand-in for all earlier Figure systems, other manufacturers, or the best alternative that could have been trained with a different method. Those would require their own comparisons. Nor does a large relative improvement settle the practical question. Improving from a low starting point can be an important research result while leaving many attempts incomplete.
The gap also cannot allocate credit among ingredients inside the pretraining package. To learn whether a particular type of human activity, recording perspective or data selection rule was responsible, an evaluator would need additional comparisons that change those ingredients separately. The result supports the package tested. It does not establish that every way of collecting human behavior would produce the same improvement, or that simply purchasing more recordings would reproduce it.
For a research reader, the useful follow-up is reproducibility: which training choices, data definitions and evaluation records are available to another team? For a household reader, the useful follow-up is continuity: is the policy being offered in a product actually the one evaluated? Both questions matter, but they request different evidence. A clear research protocol can support confidence in a scientific comparison without establishing the configuration delivered to a customer months later.
Unfamiliar homes are one kind of unfamiliarity
A task, an object and an environment are separate dimensions. A robot can have practiced folding without having seen your towel. It can have practiced reaching across tables without having seen your table. Calling the setting unfamiliar is therefore compatible with extensive prior learning. The important question is what was withheld and what remained familiar. Figure explicitly bounds its zero-shot claim to evaluation homes and manipulated objects, rather than saying the tasks were learned on arrival.
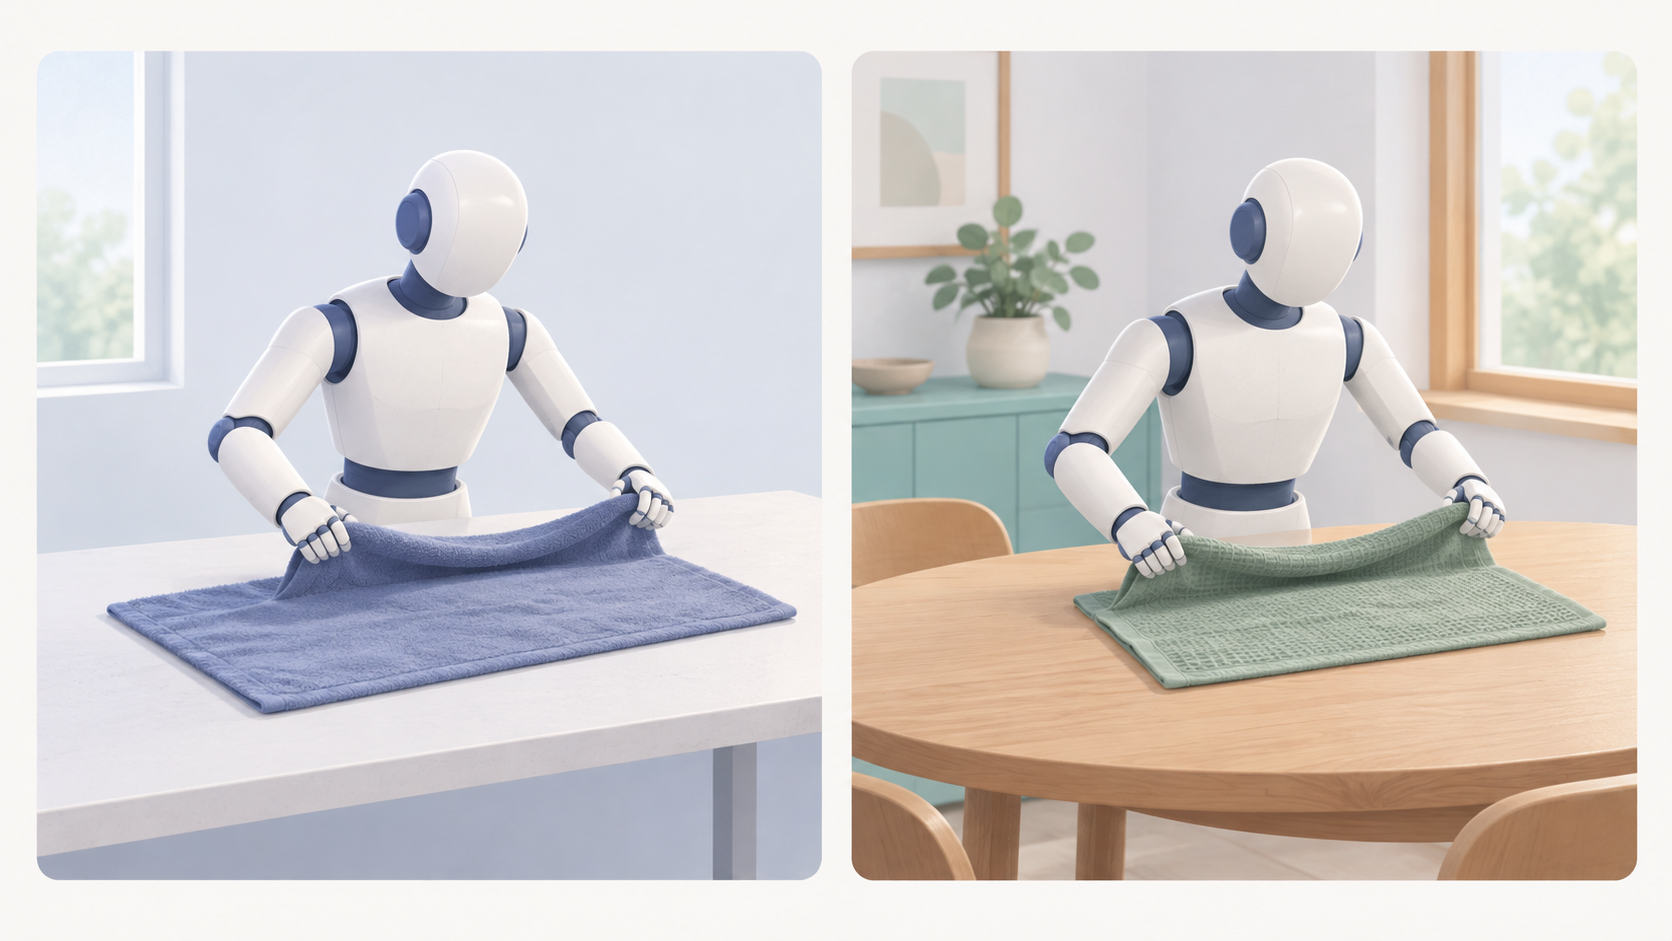
AI-generated conceptual illustration: a familiar folding task can be tested with unfamiliar objects and surroundings. These invented scenes do not depict Figure hardware or its trials, and do not establish successful completion.
This makes the reported transfer more useful to discuss precisely. It tests whether a learned behavior carries into new circumstances. It does not show that an owner can name any new chore and immediately obtain dependable results. Changing a towel's color is also not the same challenge as introducing a wet bath mat, a fragile garment or a rule about which family member owns an item. Those examples illustrate different requests; they are not additional test conditions documented in this report.
Home selection matters too. A count of homes tells you how many locations were included, but it does not establish how well they represent a particular buyer. Useful descriptive information would include access around furniture, floor transitions, lighting, room size and the arrangements the robot was allowed to change. A compact bedroom and a spacious bedroom can both be real homes while placing very different demands on reaching and repositioning.
Ask how homes entered the evaluation and which proposed settings were excluded. An exclusion is not inherently a flaw: a carefully bounded study needs a workable scope. The problem comes when the scope disappears from the conclusion. If the operating envelope excludes a feature central to your home, the trial cannot answer your question even if the aggregate result is reproducible. Likewise, testing a room with static objects does not automatically answer how the robot responds when someone moves through it during a task.
A completion score and a household standard can differ
For tidying, the desired destination is part of the job. Placing objects in a basket is a clear, observable outcome. A household may instead want objects sorted into several locations, kept away from a pet, or left untouched when ownership is uncertain. Those extra rules should be written as separate requirements. Adding them changes the task; it would be unfair both to claim the published result already covers them and to criticize the experiment for not measuring a job it did not set out to measure.
For fabric tasks, separate completion from finish quality. A towel can reach its destination and still be folded in a way the owner wants to redo. Conversely, a neat fold left on the work surface may fail a complete delivery requirement. Neither observation should disappear into a single word such as successful. A useful household record has room for both: whether the requested sequence finished and whether the resulting arrangement was acceptable without rework.
Bed making has a similar boundary. Straightening bedding is different from changing linen, fitting a sheet or identifying a spill. Before treating a bed making result as evidence for a weekly routine, list the actual operations that routine includes. This does not diminish a successful manipulation sequence. It prevents an ordinary phrase from carrying more capability than the evaluated sequence demonstrates.
Time limits should be read as rules for scoring, not as typical completion times. Knowing the allowed time does not tell you the median duration, the slow end of the distribution or the time spent preparing and resetting the scene. A buyer assessing usefulness needs those separately. If a robot works slowly but requires no attention, that can have a different value from a faster sequence that repeatedly calls the owner back. Elapsed time and human attention are two different costs.
The missing shape behind an average
Repeated trials within a home are valuable: they can expose sensitivity to object arrangements or repeated mistakes. They are not equivalent to adding more independent homes. Two attempts in the same bedroom share furniture, lighting and access constraints. Without the distribution of trials and outcomes by home, the pooled score cannot tell you whether performance was broadly consistent or concentrated in a subset of favorable settings.
This is why a more detailed report would be useful even without a new headline number. A task-by-home table could show whether a failure travels with a particular room, a particular object arrangement or a particular behavior. Recording exclusions and aborted trials would help establish the denominator. Recording why each attempt ended would distinguish a timeout from a perception mistake, a dropped item or a stop requested by an operator. These are suggested reporting categories, not a claim that Figure observed each failure type.
Avoid calculating a household forecast by treating every attempt as an interchangeable coin toss. That assumption would require evidence that the attempts were sufficiently comparable and independent for the proposed use. Repeated difficulty with one layout may persist, rather than disappearing with another try. Likewise, multiplying separate task rates to predict a whole day's chores adds assumptions about independence and sequencing that this study does not establish.
A useful estimate for your own setting would therefore start with a matching scenario and repeated observations, not with a more elaborate calculation on an unmatched headline rate. The precision of a decimal is not a substitute for knowing what was tested. Until more granular records are available, the appropriate reading is that these outcomes describe the reported experiment; they are not calibrated odds for every household.
Recovery, supervision and safe stopping
A robot changing its approach can be an important part of a successful task. The practical question is whether the correction resolves the problem within the agreed conditions. Watching a single successful recovery does not reveal how often recovery was needed, how often it failed, or whether unsuccessful attempts required someone to restore the environment. Request the frequency and outcome together. Otherwise, a compelling recovery clip can hide the same selection problem as a compelling first attempt.
For any supervised trial, distinguish an observer from a helper. Someone watching without intervening is different from someone pointing to an object, moving a basket or physically repositioning the robot. The report treats safety intervention as failure, which is a meaningful scoring rule. That rule does not by itself measure the risk of unsupervised operation or establish that no supervision is required. Outcome accounting and permission to operate are separate questions.
An owner should request the supplier's instructions for stopping, restarting and handling an incomplete task. Do not improvise a physical test of collision behavior or obstacle handling to fill a missing safety record. Ask what the manufacturer permits, what conditions require an operator and what the robot is expected to do when it cannot continue. The purpose of an in-home evaluation is to assess a supported workflow, not to invent a stress test around people, animals or valuable objects.
A practical record for an offered home trial
If a supplier offers a supported trial, choose one recurring chore whose value you can explain. Write down how you currently finish it and which part you want to delegate. For example, the objective might be folded towels in a designated basket, ready for a person to store. That deliberately leaves storage outside the requested service. A different household might need shelf placement too. Making the boundary explicit gives both households a fair way to judge their own result.
Before starting, agree with the supplier on the allowed objects, placement, operating conditions and intervention procedure. Record the hardware and software version supplied for the trial. If someone prepares the room or sorts the objects, include that preparation in the account. There is no need to pretend preparation makes the result worthless; it simply consumes time and changes what has been delegated.
Use a short record that can be repeated across attempts:
Field
Requested outcome
- What to record
- Objects, destination and acceptable finish
- What it helps decide
- Whether the work matches your actual need
Field
Preparation
- What to record
- Time and changes made by people before starting
- What it helps decide
- Whether convenience depends on extra setup
Field
Execution
- What to record
- Start, finish or stop time; completed items
- What it helps decide
- Whether duration fits your routine
Field
Assistance
- What to record
- Who helped, when, why and for how long
- What it helps decide
- How much attention remains with people
Field
Result
- What to record
- Complete, incomplete, refused or stopped; quality of finish
- What it helps decide
- What work is left afterward
Field
Restoration
- What to record
- Cleanup, reset and any supplier follow-up
- What it helps decide
- The full burden of an unsuccessful attempt
| Field | What to record | What it helps decide |
|---|---|---|
| Requested outcome | Objects, destination and acceptable finish | Whether the work matches your actual need |
| Preparation | Time and changes made by people before starting | Whether convenience depends on extra setup |
| Execution | Start, finish or stop time; completed items | Whether duration fits your routine |
| Assistance | Who helped, when, why and for how long | How much attention remains with people |
| Result | Complete, incomplete, refused or stopped; quality of finish | What work is left afterward |
| Restoration | Cleanup, reset and any supplier follow-up | The full burden of an unsuccessful attempt |
Keep refusals visible. Declining an unsupported request may be appropriate behavior, but the household still needs another way to complete that chore. Keep rework visible too. If you fold half the towels again afterward, count that as remaining work rather than silently changing your standard to match the machine. The useful decision is whether the supported service improves your routine, not whether you can find a definition that makes every demonstration look successful.
Finally, compare the observation with the exact written offer. Ask whether the trial uses a specialist configuration, whether updates can change supported behaviors, and whom you contact if a previously working task stops working. Clarify repair arrangements, transport responsibility, expected downtime and any recurring software or assistance fees. This report provides no retail service agreement, so those remain questions for an actual supplier offer. A household can appreciate the research progress while keeping a purchasing decision open.
The Figure 03 profile and Figure AI manufacturer page provide starting points for checking product records and their sources. A catalog status such as Active is not a promise of consumer availability. For a comparison, retain each price's currency and check whether the listed configuration includes the demonstrated capability; do not infer software access from a hardware listing.
Questions buyers may still have
Does this establish general home autonomy?
A bounded evaluation cannot establish unrestricted household operation. Ask which chores, rooms and conditions are supported, what requires supervision, and what the system must refuse. Cooking, care work or handling valuables should not be assumed from success at another task.
Can I rank other robots against this percentage?
Only a matched protocol makes that comparison meaningful. Different objects, time limits, grading rules and intervention policies can change the question being measured. Put unmatched results side by side as evidence descriptions, not a performance leaderboard.
Is this a retail announcement or independent review?
The cited evidence is a manufacturer research report. A buying decision needs separate, current commercial terms and evidence from use outside the supplier's evaluation. ui44 did not operate the robot or reproduce the experiment.
Source and update note
Source
Figure's Helix 2.5 report, results chart and appendix
- Evidence type
- Primary; manufacturer research
- Dates
- Published September 17, 2026; checked October 11, 2026
| Source | Evidence type | Dates |
|---|---|---|
| Figure's Helix 2.5 report, results chart and appendix | Primary; manufacturer research | Published September 17, 2026; checked October 11, 2026 |
Revisit this analysis when Figure reconciles the baseline percentage, or when independent replication or consumer delivery terms provide new evidence.
Written by
ui44 Team
Published October 10, 2026
Share this article
Open a plain share link on X or Bluesky. No embeds, no widgets, no cookie baggage.